Stackable
Now available: Stackable Data Platform 26.7 → SLSA provenance, dynamic image repositories & more!
Jetzt verfügbar: Stackable Data Platform 26.7 → SLSA-Provenance, dynamische Image-Repositories & mehr!
Data Lakehouse technology showcase
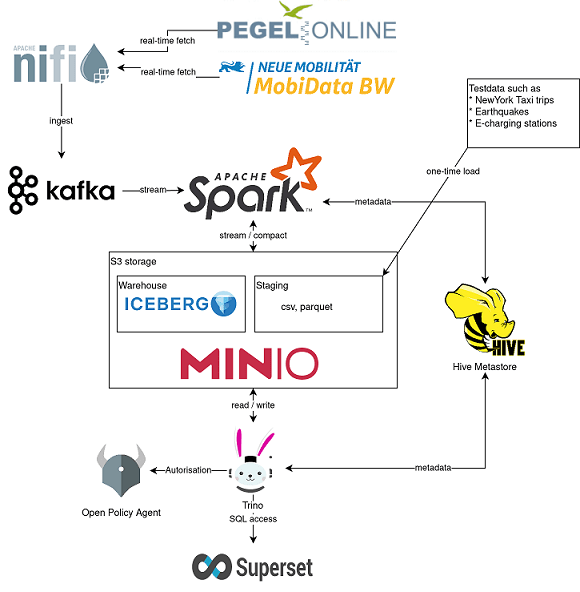
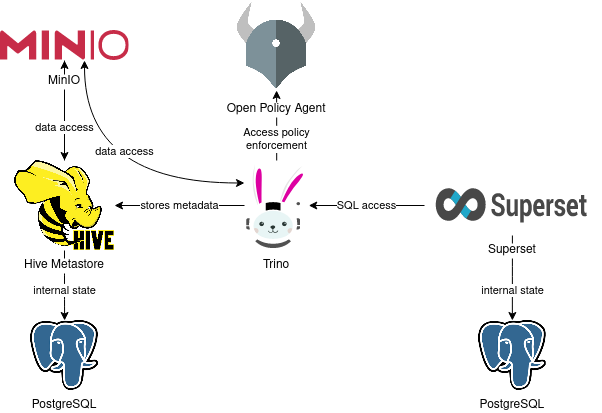
A modern lakehouse blueprint: Apache NiFi streams data into Apache Iceberg tables on S3, Trino queries them with full SQL, and Superset turns them into dashboards, with schema evolution and time travel built in.
HOW TO START
With a Kubernetes cluster, run a single command:
Key Features
Open table format
Apache Iceberg brings ACID, schema evolution and time travel to the lake.
Warehouse SQL on the lake
Trino queries Iceberg directly, with no copies and no separate warehouse.
Schema evolution
Add or rename columns without rewriting the data.
Streaming ingestion
NiFi continuously lands data into Iceberg tables.
Time travel
Query any historical snapshot of a table.
Self-service BI
Superset dashboards built directly on top of Trino.
Demo Components
Apache Iceberg
Table format
Open table format providing ACID transactions, schema evolution and snapshot time travel.
Apache NiFi
Ingestion
Flow-based ingestion streaming source data into the Iceberg tables.
Trino
Query engine
Distributed SQL engine querying Iceberg tables with full ANSI SQL.
Apache Superset
BI
Dashboards and exploration built on the Trino connection.
Demo Workflow
Installation
One command installs NiFi, Iceberg-backed storage, Trino and Superset.
Ingest with NiFi
Watch NiFi stream source data into Iceberg tables on S3.
Query in Trino
Run full SQL against the Iceberg tables, no data movement required.
Time-travel a snapshot
Query an earlier snapshot to see the table as it was.
Explore the dashboard
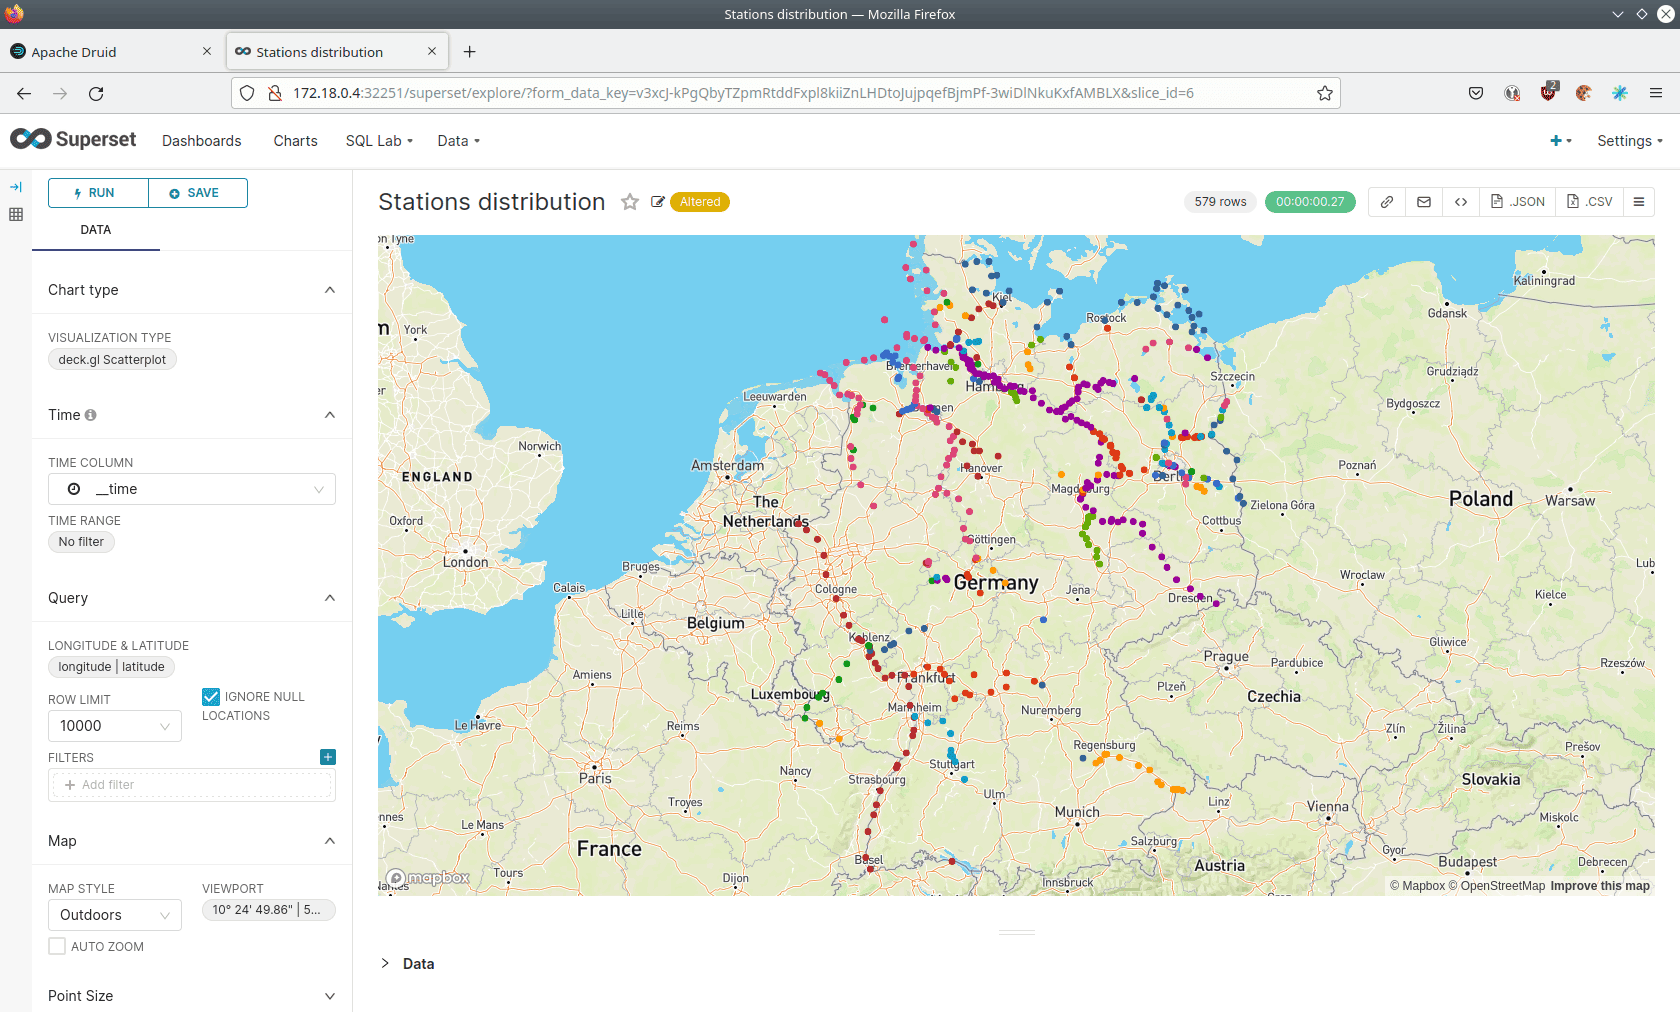
Open the pre-built Superset dashboard on top of the lakehouse.
Build a lakehouse that combines streaming ingestion with warehouse-grade SQL.