Stackable
Now available: Managed Data Lakehouse → Sovereign, Compliant, Open Source. Try it free for 30 days.
Jetzt verfügbar: Managed Data Lakehouse → Souverän, Compliant, Open Source. 30 Tage kostenlos testen.
Machine Learning for outlier detection
Unsupervised outlier detection on New York taxi data: Apache Spark trains an isolation forest, the results land in Apache Iceberg, and Superset visualizes the anomalies.
HOW TO START
With a Kubernetes cluster, run a single command:
Key Features
Unsupervised ML
An isolation forest needs no labelled data to find outliers.
Iceberg result store
Predictions are persisted as an open Iceberg table.
Reproducible
Pinned images and declarative jobs make runs repeatable.
Distributed training
Spark scales the training job across the cluster.
Visual review
Superset charts the flagged outliers for inspection.
Extensible
Swap in your own model or dataset with minimal change.
Demo Components
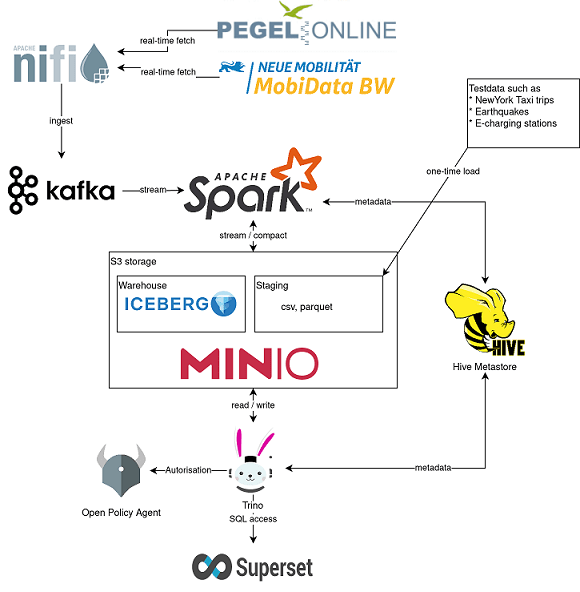
Apache Spark
ML compute
Trains the isolation-forest model as a distributed Spark job.
Apache Iceberg
Result store
Stores model predictions as an open, queryable table.
Apache Superset
Visualization
Visualizes the flagged anomalies against the raw trips.
MinIO
Data lake
S3-compatible object store holding the taxi dataset.
Demo Workflow
Installation
One command installs Spark, Iceberg-backed storage and Superset.
Load taxi data
The demo loads the New York taxi dataset into the lake.
Run the Spark job
Train the isolation forest as a distributed Spark job.
Write to Iceberg
Persist the anomaly predictions to an Iceberg table.
Explore anomalies
Inspect the flagged outliers in the Superset dashboard.
Run a full ML batch pipeline on the platform, from training to dashboard.