Stackable
Now available: Stackable Data Platform 26.7 → SLSA provenance, dynamic image repositories & more!
Jetzt verfügbar: Stackable Data Platform 26.7 → SLSA-Provenance, dynamische Image-Repositories & mehr!
Analysis with a data lake
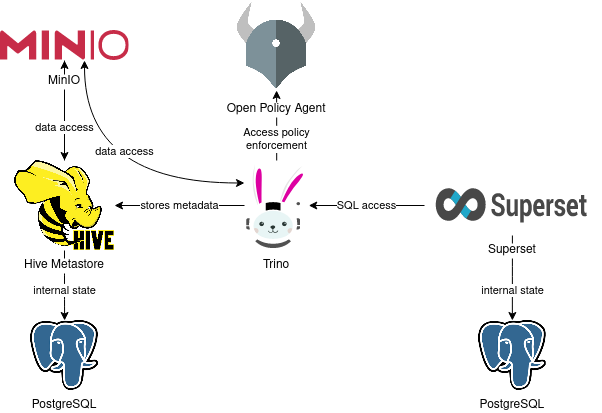
Data sitting in S3 analyzed all the way to a dashboard: Trino queries Parquet files directly via a Hive metastore, with role-based access enforced by Open Policy Agent, visualized in Superset.
HOW TO START
With a Kubernetes cluster, run a single command:
Key Features
Query files in place
Trino reads Parquet on S3 directly, with no loading step.
Role-based access
Open Policy Agent enforces who can query what.
BI-ready
Superset dashboards built straight on top of Trino.
Hive metastore
A schema catalog over the raw files in the lake.
Federated SQL
Join across multiple sources in a single query.
Open formats
Parquet on S3, with no proprietary storage and no lock-in.
Demo Components
Trino
Query engine
Distributed SQL engine querying Parquet files on S3 in place.
Catalog
Provides the schema catalog that maps SQL tables to files.
MinIO
Storage
S3-compatible object store holding the Parquet dataset.
Open Policy Agent
Authorization
Enforces role-based access control over the Trino catalog.
Demo Workflow
Installation
One command installs Trino, the Hive metastore, OPA and MinIO.
Catalog the data
The metastore exposes the S3 Parquet files as SQL tables.
Query with Trino
Run full SQL against the files without moving any data.
Hit an access boundary
See a restricted query denied by the OPA policy.
Explore the dashboard
Open the Superset dashboard built on the governed catalog.
Query files in object storage with full SQL and governed access.